
N+1 vs 2N UPS Redundancy: Which Level Does Your Project Need?
Redundancy levels are often quoted as marketing labels—the engineering reality is a cost-versus-failure-mode decision that your project can actually compute
Introduction
Few terms in critical power are used as loosely as redundancy. Sales sheets say “N+1” or “2N” as if the letters were quality grades; project documents copy whichever figure the previous design used. Yet these levels describe genuinely different machines—not just different prices, but different behavior on the day something fails. The level you choose determines which failures your facility shrugs off, which ones reach the load, how maintenance gets scheduled, and how much of the budget went into capacity that will never carry load until its twin is broken.
Choosing wrong costs money in both directions. Over-redundancy ties up capital, floor space and engineering attention in a second power system that a modest service-level agreement never justifies. Under-redundancy is worse: it shows up as an outage that the wrong redundancy level had quietly promised to absorb, with a contract and a reputation attached. Between the two sits a short list of questions—what must stay up, for how long, and what the business actually loses when it does not.
This guide defines the levels precisely, compares N, N+1, 2N and 2N+1 line by line, matches levels to real uptime targets, and lists the design mistakes that quietly cancel redundant capacity. For the equipment context the UPS sits in, start from our data center power equipment range.
Redundancy in Plain Language: What the Letters Mean
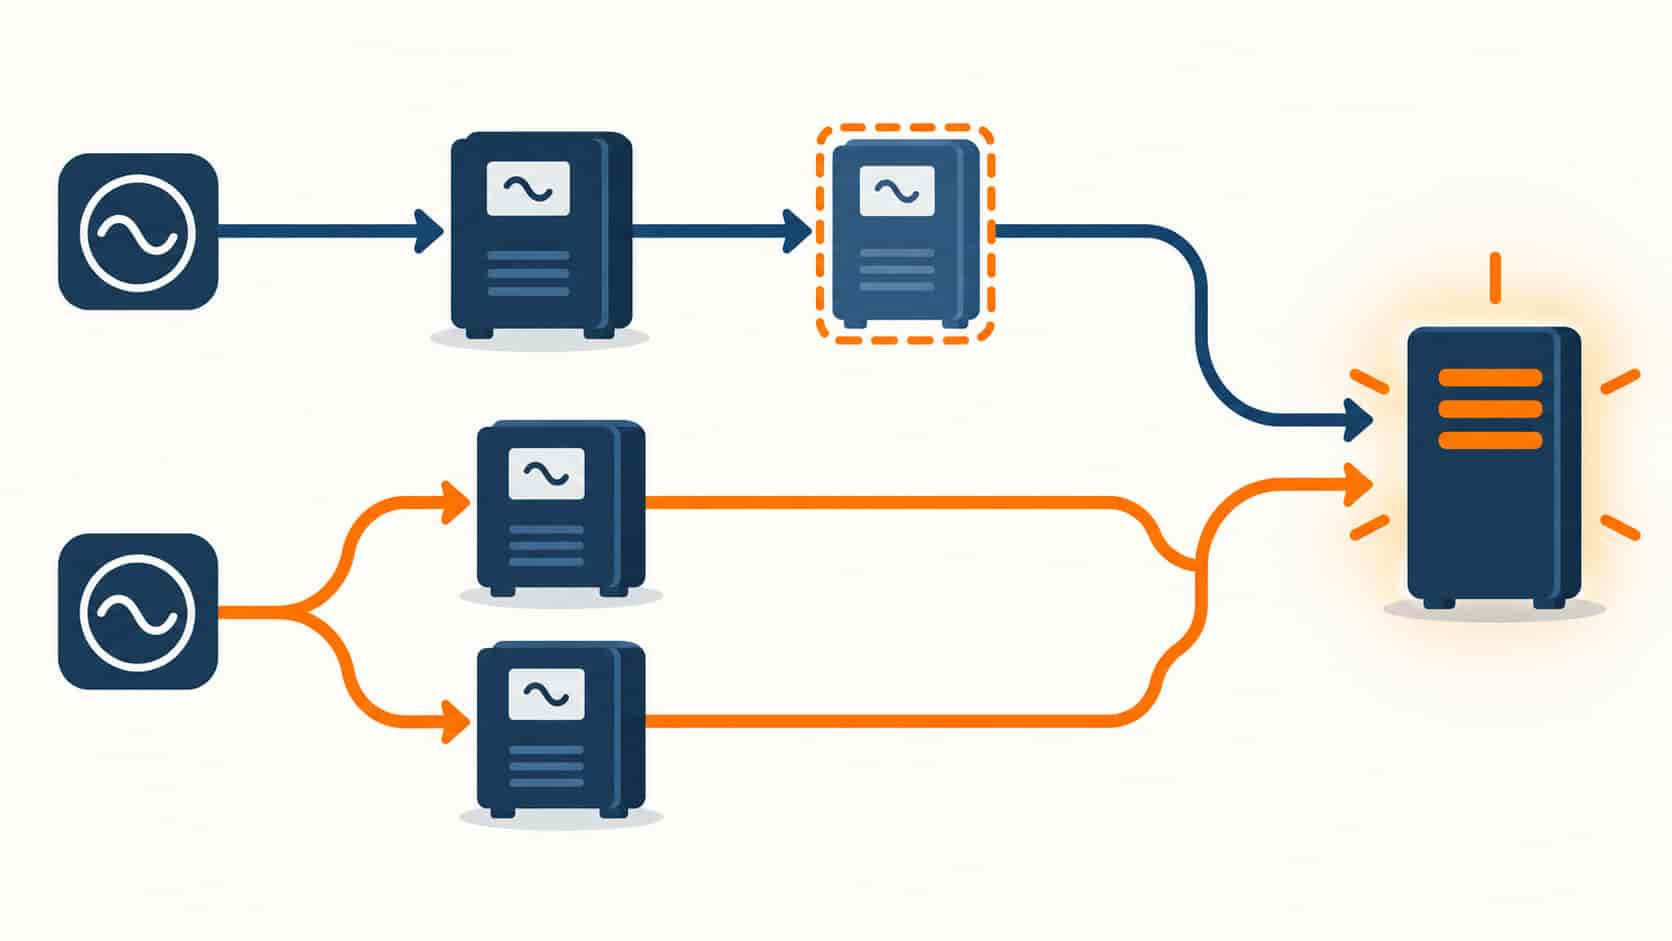
The notation is simple once stated. N is the capacity required to serve the load—nothing more. If your load is 600 kW and one 600 kW UPS serves it, that is N. N+1 adds one more unit (or module) than the load requires, so any single component can fail and the remaining capacity still carries the load. 2N duplicates everything: two complete, independent systems, each sized for the entire load, each capable of running the facility alone. 2N+1 adds a spare to each of the two worlds—the belt, the suspenders, and a third hole in the leather.
Two clarifications prevent most confusion. First, redundancy is a property of a system path, not of a cabinet: a single UPS frame with hot-swappable modules can be internally N+1, but its bypass, backplane and control remain shared elements that internal module redundancy does not cover. Second, the redundancy letter describes capacity, not independence—the independence comes from how the systems are split electrically, which is where 2N earns its price. A “2N” label on two units sharing one upstream feeder describes duplication, not resilience.
The Four Levels Compared
The levels in a single view—what each survives, what it does not, and roughly what it costs relative to a plain N system:
| Level | Architecture | Survives | Does Not Survive | Relative Cost |
|---|---|---|---|---|
| N | One path exactly sized to the load | Grid events the UPS absorbs | Any UPS component failureâload drops or rides bypass | 1.0Ã (baseline) |
| N+1 | One spare unit or module beyond load | Any single power-unit failure with capacity intact | Failure of shared elements: frame, bypass, upstream feed, battery bus | ~1.2â1.4Ã |
| 2N | Two complete independent systems, each sized for full load | Failure or maintenance of either entire system, including its bypass and feed | Common-mode causes: shared upstream source, room event, operational error | ~2.0Ã |
| 2N+1 | 2N plus one spare unit in each system | One failure inside either system while it also carries the full load alone | Only true common-mode causes above both systems | ~2.4â2.6Ã |
Read the fourth column carefully, because it is where the money lives. N+1’s unprotected list is short but pointed: everything the redundant unit shares with the primary is still a single point of failure. 2N shrinks that list dramatically by removing sharing—except the causes no amount of duplication inside the room can address, which is why the design conversation must include what happens upstream of the UPS room, not only inside it.
What N+1 Actually Buys—and What It Does Not
N+1 is the workhorse level of the industry for good reason: it converts the most likely failure mode—a single power unit going down—from a load event into a maintenance ticket. With a spare unit (or module) beyond the load requirement, one failure changes nothing for the servers, and the repair becomes a planned activity instead of an emergency. For the majority of commercial data centers and enterprise facilities, this is precisely the failure coverage the business case needs, at roughly 20–40% cost premium rather than a doubling.
What N+1 does not buy is equally concrete. The shared elements remain unprotected: the frame electronics of a modular system, the static bypass, the upstream feeder and switchgear, the battery strings if they are common, and the physical room itself. Maintenance of those shared elements still requires load transfer to bypass—the famous “windows of reduced protection” that serious operations track and minimize. And if two power units fail close together, or one failure coincides with a maintenance window, N+1 has no further layers. It buys one failure, cleanly handled; it does not buy independence.
What 2N Buys: Two Independent Worlds
2N’s engineering argument is not “two of everything” but “two of everything that never touches.” Two complete systems—feeds, UPS, distribution, batteries—arranged so that no single physical or electrical event can reach both. The load has two power supplies or a transfer path between paths, and either world can vanish entirely: for maintenance, for upgrade, for a flooded room—while the other world simply keeps running. Maintenance stops being a risk window and becomes a routine, because the system being serviced is not the system carrying the load.
The price is literal: roughly double the UPS hardware, double the batteries and floor area, and often a more complex switchgear scheme to keep the worlds separated down to the room level. It also changes operational discipline—concurrent maintainability is a design property that must be verified in operation, not assumed from the label, because a technician jumpering between worlds “temporarily” can silently convert 2N back into N. Facilities that genuinely need 2N—financial trading, Tier IV commitments, contracts with per-minute penalties—buy it knowingly; facilities that do not, often discover the operational overhead without the corresponding revenue.
Matching Redundancy to Uptime Targets
The redundancy level is a business decision wearing an engineering costume. Start from the service commitment: what does the contract, the regulator or the business actually promise, and what does one minute of downtime cost? A facility selling 99.99% availability has a yearly downtime budget of about 52 minutes; N+1’s single-failure coverage plus disciplined maintenance windows can live inside that. A 99.999% commitment—five minutes a year—cannot tolerate the reduced-protection windows N+1 requires, and 2N becomes the honest answer rather than a luxury.
Then look at what happens after the UPS bridge: the level of redundancy upstream and in the energy tier must match the promise. An N+1 UPS backed by a single generator and a single utility feed has a chain whose weakest link sets the real availability—our overview of data center energy storage and backup covers how generator and storage tiers fit the same logic. A common pattern for growing facilities is to build the electrical space for 2N while commissioning N+1, converting as the revenue materializes—a compromise that works only if the growth path was designed in, not retrofitted around.
The Hidden Sizing Rule: Redundant Capacity Must Carry the Load
The most common quoting error in redundant systems is arithmetic: quoting total installed capacity as if the load could use all of it. In an N+1 system, the load must run on the remaining units with one down—which means N units sized to the load, not N+1 units sharing it. The same rule runs through the whole power train: upstream switchgear, feeds and cooling for the UPS room must support the failure case, not just the happy case. The decision table below turns these rules into a starting point:
| If Your Requirement Is⦠| Sensible Level | Reasoning |
|---|---|---|
| Minutes of downtime tolerable per event; SLA around 99.9% | N with generator backup | The UPS bridge plus genset covers the realistic failure set |
| Commercial colocation or enterprise hall, 99.98â99.99% SLA | N+1 | Single-failure coverage with disciplined maintenance windows fits the budget |
| Contractual Tier IV / concurrent maintainability commitments | 2N | Maintenance without load transfer is the commitment itself |
| Trading floor, payment core, per-minute penalty contracts | 2N or 2N+1 | Independent worlds plus internal spares against stacked failures |
| Growth-stage facility, capital constrained today | N+1 now, 2N-ready space | Buy the failure coverage you sell; reserve the path to independence |
| Industrial process with batch-costânot per-minuteâlosses | N+1 on critical bus only | Protect the process bus; tolerate transfer windows on auxiliary loads |
The Mistakes That Cancel Redundancy
Redundant hardware can be silently de-redundized by design and operation choices, and the list is depressingly familiar. Both “independent” systems fed from the same upstream transformer or the same room’s single switchboard—the common-cause failure that no UPS-level duplication survives. Battery strings shared or co-located so one event—thermal runaway, water ingress, a dropped cabinet—hits both worlds. Maintenance procedures that parallel the two systems through temporary cabling to avoid a transfer window, converting a designed 2N into an accidental N with extra steps. And monitoring that watches each unit but not the separation itself, so the first sign of a bridged system is the event that proves it.
The operational error category deserves its own emphasis: studies of data center outages consistently find human action during maintenance among the leading causes. A redundancy level is only as good as the procedures that preserve it—locking rules, two-person verification on cross-connections, and periodic failure drills that exercise the spare path rather than trusting it. Procurement can buy the letters; only operations keep them true. And because large frames and switchgear for either level share today’s constrained manufacturing queues—our 2026 lead-time review has the numbers—decide the level early: changing it after order placement is expensive in both directions.
Redundancy Specification Checklist
Before comparing quotations at any level, make these explicit:
- The load and the promise: kW at stated power factor, growth horizon, and the SLA or business requirement the redundancy must honor.
- The level, spelled out: N, N+1, 2N or 2N+1 defined at system level—units, modules, bypasses, feeds and batteries included in the count.
- Independence map: a single-line showing where the two paths separate and rejoin; every shared element named and justified.
- Failure-case sizing: confirmation that N units carry the load with one unit out, including upstream feeds and breaker ratings.
- Battery strategy: strings per system, physical separation, and failure-case runtime with one system down.
- Maintenance windows: which service activities require load transfer, and how the design minimizes reduced-protection time.
- Test plan: FAT and commissioning scenarios that actually open the failure paths—pull the module, feed the load from system B—witnessed and logged.
- Operations package: switching procedures, lockout rules for cross-connections, and training that treats the redundancy as a system to preserve.
When Even 2N Is Not Enough
2N is the ceiling most facilities need, and it is worth being honest about what sits above it. True common-mode events—regional grid collapse, flood or fire at the building, coordinated operational error—can reach both worlds, which is why the highest-availability designs add geographic or diversity measures: separated rooms or floors, feeds from different substations, storage or generator tiers with different fuel and failure modes. Our review of generator and storage hybrid systems shows how source diversity, not just path duplication, hardens the energy tier.
The final layer is procedural rather than electrical: the most expensive residual risk in even a 2N facility is the untested recovery plan. Redundancy answers component failure; rehearsals answer the compound event where the spare path, the procedure and the people all meet for the first time. Facilities that drill failovers schedule them; facilities that do not, meet the failover when it is already an incident.
Conclusion
N+1 and 2N are answers to different questions. N+1 answers “can one failure occur without consequence?”—and for most commercial facilities, that is the question their SLA actually asks, answered at a fraction of duplication cost. 2N answers “can we do anything—maintain, upgrade, lose a room—without the load ever knowing?”—a stronger promise with a doubled bill and an operational discipline to match. The letters are cheap; the engineering behind them—independence, failure-case sizing, preserved separation—is the purchase.
Start from the downtime budget, work the levels against it, and verify the result up and down the power train, not just across the UPS row. When you are ready to price the system, the team at KXY E-Power Group supplies UPS systems at every redundancy level, together with the switchgear, transfer and storage equipment that keeps the redundancy real.
Frequently Asked Questions
Recent Posts
Voltage Stabilizers vs UPS: Do You Need Both?
Voltage Stabilizers vs UPS: Do You Need Both? One device fixes how high or low the voltage is; the other fixes whether there is voltage
Energy Storage for Data Centers: A Growing Backup Power Option
Energy Storage for Data Centers: A Growing Backup Power Option Batteries have always backed up data centers in the form of UPS strings. Grid-scale BESS
Thermal Runaway in Lithium Batteries: What BESS Buyers Should Understand
Thermal Runaway in Lithium Batteries: What BESS Buyers Should Understand How thermal runaway starts, how it propagates, and which evidence buyers should require before approving