
Choosing a UPS Supplier for a Multi-Site Data Center Rollout
Buying one UPS is a product decision; buying the same UPS for eight sites is a supply chain decision, and the criteria are not the same
Introduction
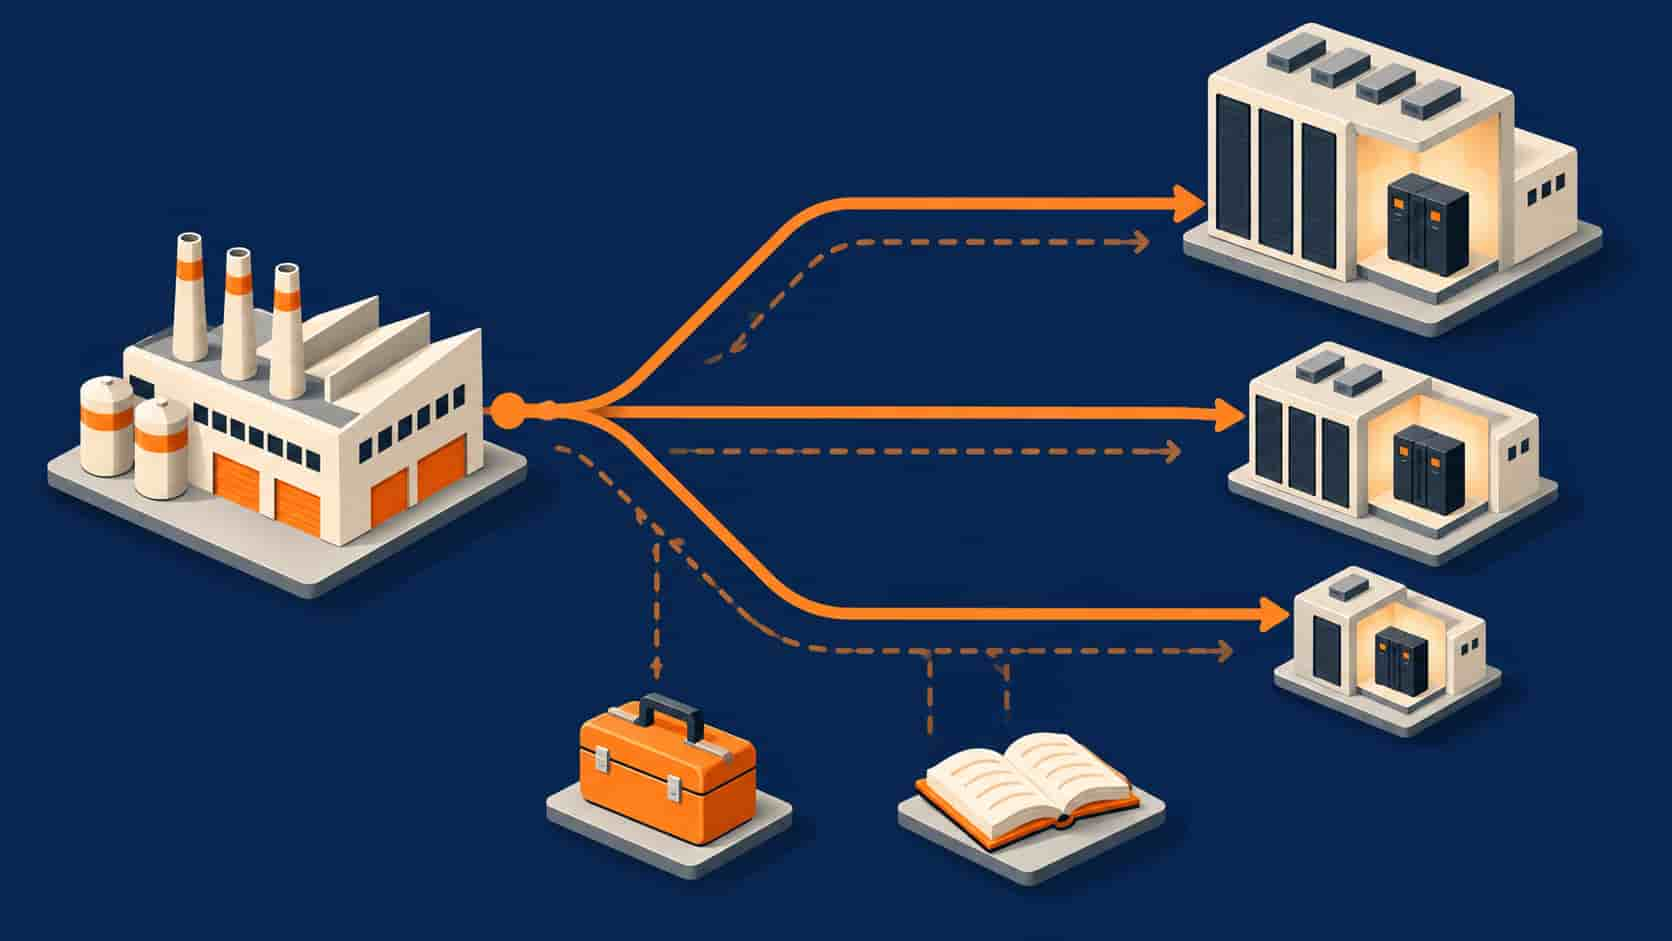
A single-site UPS purchase is straightforward: match the load, compare two or three vendors on price and delivery, install. A rollout across several sites changes the problem completely. Now the same equipment must arrive at staggered dates in different countries, be commissioned by different local teams, be maintained by people who did not attend the original training, and remain supportable for a decade during which the supplier relationship may be tested by a single failure at the worst possible site.
Multi-site buyers discover—usually the hard way—that the real cost of a rollout is not the unit price of the UPS. It is the cost of divergence: six sites with four firmware versions, three battery types, two monitoring systems and no shared spares pool. Every saving made by buying site-by-site gets repaid with interest in maintenance complexity, and the compounding is unforgiving because each new site multiplies the combinations.
This guide sets out how to structure a multi-site UPS procurement so that standardization works for you rather than against you: what to standardize and what to allow to vary, how to evaluate a supplier’s capacity to actually deliver a programme rather than a shipment, and which commercial and technical terms separate a real framework partner from a vendor who happens to have quoted well. For equipment context, see our data center and critical power range.
Why Multi-Site Procurement Is a Different Problem
The unit economics invert. On a single site, the lowest purchase price usually wins. Across a programme, total cost of ownership dominates: spares holdings, training, documentation consistency, monitoring integration and the engineering hours spent reconciling differences all scale with the number of variants rather than the number of units. A slightly higher unit price that eliminates two variants can pay for itself within the first year of operation. The same logic applies to lead times, where a single supplier capable of holding slots across a programme avoids the schedule fragmentation described in our analysis of switchgear lead times in 2026.
Timing becomes a constraint, not a detail. Rollouts are usually sequenced to construction completion, which means the supplier must hold a production slot structure across months and continents rather than deliver once. Suppliers who can meet a single shipment date often cannot meet a schedule of dates, and discovering this mid-programme is expensive because there is no second supplier already tooled up and approved.
Support must be distributed. A single-site buyer can accept a supplier whose service engineer is two hours away. A multi-site operator needs either local service capability at each site or a spares-and-training model that lets local technicians perform first-line work. This is frequently the criterion that eliminates the cheapest bid, and it deserves to be tested explicitly rather than assumed.
The weakest site defines the reputation. In a rollout, one UPS that fails badly at one site becomes the programme’s story regardless of how well the other seven performed. That asymmetry justifies spending more on consistency and support than a purely financial analysis would recommend—and it is the same reasoning that makes switchgear and transformer lead times a programme-level rather than site-level risk, as covered in switchgear versus transformer lead times for EPC contractors.
What to Standardize and What to Let Vary
Total standardization is neither achievable nor desirable—sites differ in capacity, climate, grid quality and local code. The skill is in drawing the line deliberately.
Standardize the platform. One UPS family across all sites, ideally with a modular architecture so that capacity differences are met by adding modules rather than by changing product lines. This preserves a single training syllabus, one spares catalogue, one firmware stream and one monitoring interface—the four things that generate most of the multi-site operating cost.
Allow capacity to vary. Sites will differ in IT load; that is expected. What should not vary is the topology family and the control philosophy. A 400 kW site and a 1.2 MW site can share the same platform if the product line scales.
Hold the battery specification, but expect the market to intrude. Battery availability, transport restrictions and recycling rules differ by country. Decide in advance which deviations are acceptable—typically chemistry and monitoring must stay standard while the specific block model may vary—and record the decision so the eighth site does not reopen it.
Keep monitoring and interfaces rigid. If sites report to a central NOC, the protocol, alarm taxonomy and data points must be identical everywhere. Retrofitting consistency into a monitoring layer after the fact is one of the more painful and avoidable tasks in a data centre programme.
Evaluating a Supplier's Programme Capability
| Criterion | What to Ask For | Red Flag | Why It Matters at Scale |
|---|---|---|---|
| Platform consistency | Evidence of one product family meeting the full capacity range of the programme | A different model line proposed for each site | Variants multiply training, spares and documentation cost |
| Production capacity and slots | A schedule showing committed build slots against your rollout dates | Willingness to promise dates without a slot plan | Delayed sites cascade through the construction programme |
| Type-tested documentation | Certificates and test reports reusable across sites and jurisdictions | Per-site re-testing proposed as routine | Duplicate approvals consume engineering budget for no gain |
| Spares strategy | Recommended holding list, criticality tiers, and lead times per item | No distinction between critical and routine spares | One missing module can idle a whole site |
| Service model | Named support structure, escalation path, and local capability per region | A single distant service point for all sites | Response time, not price, dominates outage cost |
| Monitoring compatibility | Open protocols and a defined data model for central integration | Proprietary-only interface, no documentation | Retrofitting consistency later is slow and costly |
| Training and handover | A repeatable training package and language coverage for each region | Training tied to one site or one engineer | Knowledge must survive staff turnover |
| Commercial framework | Agreed unit pricing, escalation mechanism and change-order process | Price validity too short for a phased rollout | Re-negotiating at site five destroys the programme budget |
The Commercial Structure: Framework, Not Repeat Orders
A rollout should be governed by a framework agreement rather than a series of purchase orders, because the terms that matter are the ones that survive the first delivery. The framework fixes unit pricing with a defined escalation mechanism tied to a published index, commits production slot structure against the rollout schedule, sets the change-order process for the inevitable capacity adjustments, and defines the warranty and service obligations that apply uniformly at every site.
Two clauses deserve particular attention. The first concerns price validity across the programme: a quotation valid for thirty days is meaningless for a two-year rollout, and a supplier who will not commit to an escalation formula is transferring commodity risk to you without saying so. The second concerns continuity of support—what happens if the product line is superseded mid-programme, whether spare parts remain available for the stated service life, and how firmware and monitoring compatibility will be maintained across sites running different batches.
Payment and delivery terms also interact with rollouts in ways single-site buyers never encounter. Staggered delivery schedules, partial shipments, storage at site and staged acceptance testing all need to be written down, because “delivery” means different things to a supplier shipping once and a buyer receiving eight times. Where letter of credit or staged payment applies, the milestones should track the rollout’s actual gates rather than arbitrary percentages.
Logistics, Commissioning and Site Readiness
Delivery is not the end of the supplier’s obligation. A UPS arriving at a site that is not ready for it—no environmental control, no secured storage, no electrician available—deteriorates in ways that show up at commissioning. The framework should define site readiness conditions and the point at which responsibility transfers.
Commissioning must be templated. The value of standardization is realized at commissioning, where an identical checklist, identical acceptance criteria and identical test documentation let a small central team supervise many sites. If each site is commissioned differently, the savings from common equipment evaporate precisely where the engineering hours are spent.
Witnessed testing has a multiplier here. Factory acceptance testing witnessed once for a product platform, with per-unit routine tests thereafter, is usually the sensible balance. Insisting on full witnessed FAT for every unit of a large programme is expensive and rarely adds information once the platform is proven—though the first unit and any variant should absolutely be witnessed.
Spares and training should be delivered with the first site, not the last. Establishing the spares holding and training the regional technicians early means the second site onwards benefits from an existing support structure rather than waiting for the programme to complete before anyone can maintain anything.
Where Multi-Site Buyers Get It Wrong
| Criterion | What to Ask For | Red Flag | Why It Matters at Scale |
|---|---|---|---|
| Platform consistency | Evidence of one product family meeting the full capacity range of the programme | A different model line proposed for each site | Variants multiply training, spares and documentation cost |
| Production capacity and slots | A schedule showing committed build slots against your rollout dates | Willingness to promise dates without a slot plan | Delayed sites cascade through the construction programme |
| Type-tested documentation | Certificates and test reports reusable across sites and jurisdictions | Per-site re-testing proposed as routine | Duplicate approvals consume engineering budget for no gain |
| Spares strategy | Recommended holding list, criticality tiers, and lead times per item | No distinction between critical and routine spares | One missing module can idle a whole site |
| Service model | Named support structure, escalation path, and local capability per region | A single distant service point for all sites | Response time, not price, dominates outage cost |
| Monitoring compatibility | Open protocols and a defined data model for central integration | Proprietary-only interface, no documentation | Retrofitting consistency later is slow and costly |
| Training and handover | A repeatable training package and language coverage for each region | Training tied to one site or one engineer | Knowledge must survive staff turnover |
| Commercial framework | Agreed unit pricing, escalation mechanism and change-order process | Price validity too short for a phased rollout | Re-negotiating at site five destroys the programme budget |
Optimizing each site independently and calling it a rollout, then paying for the divergence in spares and training for a decade. Awarding on unit price with no framework, so that every site reopens commercial negotiation. Accepting a different battery model at each site because local availability made it convenient, and losing the shared spares pool in the process. Deferring the monitoring integration question, then discovering at site three that the central NOC cannot read two of the sites’ data. Treating the supplier’s service network as a commercial detail rather than a technical requirement, and discovering the gap during the first significant failure. And specifying a single global FAT regime without recognizing that regulatory approval requirements genuinely differ by jurisdiction—the fix is to identify where re-testing is compulsory and where it is merely habitual.
Specification Checklist
Bring these to the framework negotiation:
- Programme scope: site list with capacities, target energisation dates, and the capacity growth expected at each site over the framework term.
- Platform commitment: one UPS family covering the full capacity range, with the modular expansion path stated.
- Standardized elements: topology, control philosophy, battery chemistry and monitoring protocol—listed explicitly as non-negotiable, with allowed local deviations named.
- Commercial terms: unit pricing with a defined escalation index, price validity across the rollout, change-order process, and warranty scope applying uniformly.
- Delivery and logistics: slot structure against dates, Incoterms per site, storage and site-readiness conditions, and responsibility transfer points.
- Service and spares: spares holding list by criticality, regional support structure and escalation path, training package with language coverage.
- Documentation and compliance: type-test certificates reusable across jurisdictions, per-site approval requirements identified up front, as-built documentation language.
Conclusion
Choosing a UPS supplier for a multi-site rollout is less a product selection than a decision about how much operational complexity you want to own. Standardize the platform, the battery specification and the monitoring interface; allow capacity and local market conditions to vary within declared limits; and judge suppliers on programme capability—slots, spares, service reach, documentation reuse—rather than on the price of a single unit. That is the difference between a rollout that gets easier with each site and one that gets more expensive.
The strongest indicator of a supplier who can support a programme is whether they engage with the programme at all—whether the conversation moves from unit specifications to slot plans, spares lists and escalation paths. The same applies to the battery side of the scope, where chemistry and block availability vary by market; our checklist for questions to ask a battery storage manufacturer covers the equivalent due diligence on that element. KXY E-Power Group supplies UPS systems for single sites and multi-site data centre rollouts, and we would rather discuss your site schedule and spares strategy than send a catalogue. Share your rollout plan and we will respond with a framework structure rather than a price list.
Frequently Asked Questions
Recent Posts
Voltage Stabilizers vs UPS: Do You Need Both?
Voltage Stabilizers vs UPS: Do You Need Both? One device fixes how high or low the voltage is; the other fixes whether there is voltage
Energy Storage for Data Centers: A Growing Backup Power Option
Energy Storage for Data Centers: A Growing Backup Power Option Batteries have always backed up data centers in the form of UPS strings. Grid-scale BESS
Thermal Runaway in Lithium Batteries: What BESS Buyers Should Understand
Thermal Runaway in Lithium Batteries: What BESS Buyers Should Understand How thermal runaway starts, how it propagates, and which evidence buyers should require before approving